This essay is over 13,000 words long and represents our most substantial writing on AI safety since the original essay.
Over the last few months, loss–of–control incidents at OpenAI and Anthropic have intensified concerns about AI safety. Warnings about existential risk have increasingly reached the broader public, alongside calls to slow AI development. Dario Amodei’s call to “pace the frontier” reflects the concern that safety efforts are not keeping up with AI capabilities.
The most prominent example was the OpenAI – Hugging Face incident, where hundreds of OpenAI agents got access to the internet and hacked Hugging Face to find how they were being graded on an evaluation. Over the last two weeks, the details of many other instances of such activity from OpenAI agents being evaluated have surfaced, such as agents using an old Wiki website to communicate with each other despite restrictions on such activity, or attacking a software repository to attempt to upload malicious software.
The AI safety community has viewed these incidents largely as a crisis for alignment.1 In this view, alignment will become harder over time as agents learn to reason covertly, and as a result, loss-of-control incidents are likely to become much more widespread and damaging as agents become more capable.
On the other hand, cybersecurity practitioners have largely viewed these incidents as consequences of companies failing to adopt basic security precautions. They do not see the incidents as a sign of AI reaching a new milestone in cybersecurity. This is also the dominant reaction in the tech community outside AI, which has largely treated the incidents as a result of ineptitude and negligence by AI companies.2
Both communities have made important points. But the polarization between them is counterproductive, and there are lessons from both the alignment failure and the security failure for understanding the path forward.
In this essay, we apply the AI as Normal Technology framework to synthesize the views of the safety and cybersecurity communities and offer a constructive middle ground. We think AI companies should be liable for what their agents do, and this should be clarified through policymaking. At the same time, recognizing their responsibility does not mean that preventing future incidents is a solved problem.
We identify three areas where investment is necessary to address loss-of-control risks: research to develop better methods for controlling increasingly capable agents, translating existing research and known control techniques into usable tools, and organizational changes to ensure that these tools are actually adopted. In our view, standards for organizational governance should be a key way to pace the frontier and pull AI companies out of the “move fast and break things” attitude they currently operate in.
This essay has three parts. In Part 1, we argue that alignment alone is not enough to prevent such incidents, and discuss technical, organizational, and policy interventions for improving AI control. We are cautiously optimistic that the right investments and policy interventions can allow AI control to keep pace with AI capability improvements. In Part 2, we discuss the impact of improving AI capabilities, such as agent swarms, on cybersecurity. In Part 3, we share how our views on AI safety have changed in light of new evidence.
A summary of our argument:
-
We agree with security practitioners that OpenAI did not take adequate protections for controlling their agents. But this is not just a matter of applying 30-year-old security methods to a new domain. Security for AI agents — AI control — while important, is not a solved problem. While known control methods would have prevented the Hugging Face incident, as agent capabilities continue to advance, we will only be able to control them if we invest adequately in control interventions.
-
We also agree with security practitioners’ implicit position that these incidents are primarily a security story. In the AI safety community, rogue agents are treated as inherently catastrophic because of the assumption that there is an endless list of risks that will arise from their development. We disagree. We have long advocated that the best approach to AI safety is to identify the risks and address those specific risks. Over the last few months, it has become clear that one urgent risk is cyberoffense, because it has unique properties that allow agents to carry it out autonomously. We should similarly invest in defenses against other specific risks, such as biorisk and risks from military AI.
-
We agree with the safety community that there is an urgent need for technical and policy interventions to prevent loss-of-control incidents. But in our view, marginal investments in control are more likely to be effective compared to those in alignment. We view these incidents as illustrating the lack of emphasis on AI control within companies, despite the availability of known techniques. More broadly, there are many common-sense policy proposals that could help promote investments in AI control where we share common ground with the safety community.
-
How should we reason about AI’s impact on cybersecurity? It’s plausible that advances in agent capabilities upset the offense-defense balance for cybersecurity. We cannot yet be certain, but there is enough evidence that agent capabilities might soon make widespread cyberoffense possible that urgent action is warranted. We discuss potential interventions for tilting the offense-defense balance towards defenders.
-
How the AI as Normal Technology framework has evolved over the last year. We take stock of AI progress and share how we have updated our views. In the essay, we did not pay sufficient attention to safety risks that arise during development and evaluation (as opposed to the widespread deployment of models). We were too confident that companies would take basic control precautions and underplayed the importance of jaggedness, which led us to underestimate how quickly capabilities could improve in domains such as cybersecurity.
-
At the same time, many distinctive claims of AI as Normal Technology have held up, and it remains valuable for understanding AI’s societal impacts. In particular, we think recent incidents support our continuity hypothesis — the behavior of “rogue” agents became apparent and widely publicized while they are still far from causing serious harm and incompetent at hiding their traces. The societal reaction to even the relatively small harms from these incidents has been fierce (and the safety community deserves credit for keeping up pressure on companies). Whether this translates into meaningful changes in companies’ behavior remains an open question, and a test of the usefulness of the AINT framework.
-
Finally, we think AINT is particularly valuable for analyzing these incidents because it provides a framework for synthesizing the AI safety and cybersecurity communities’ views into a coherent plan of action: hold companies responsible, invest in control, and strengthen defenses against specific risks.
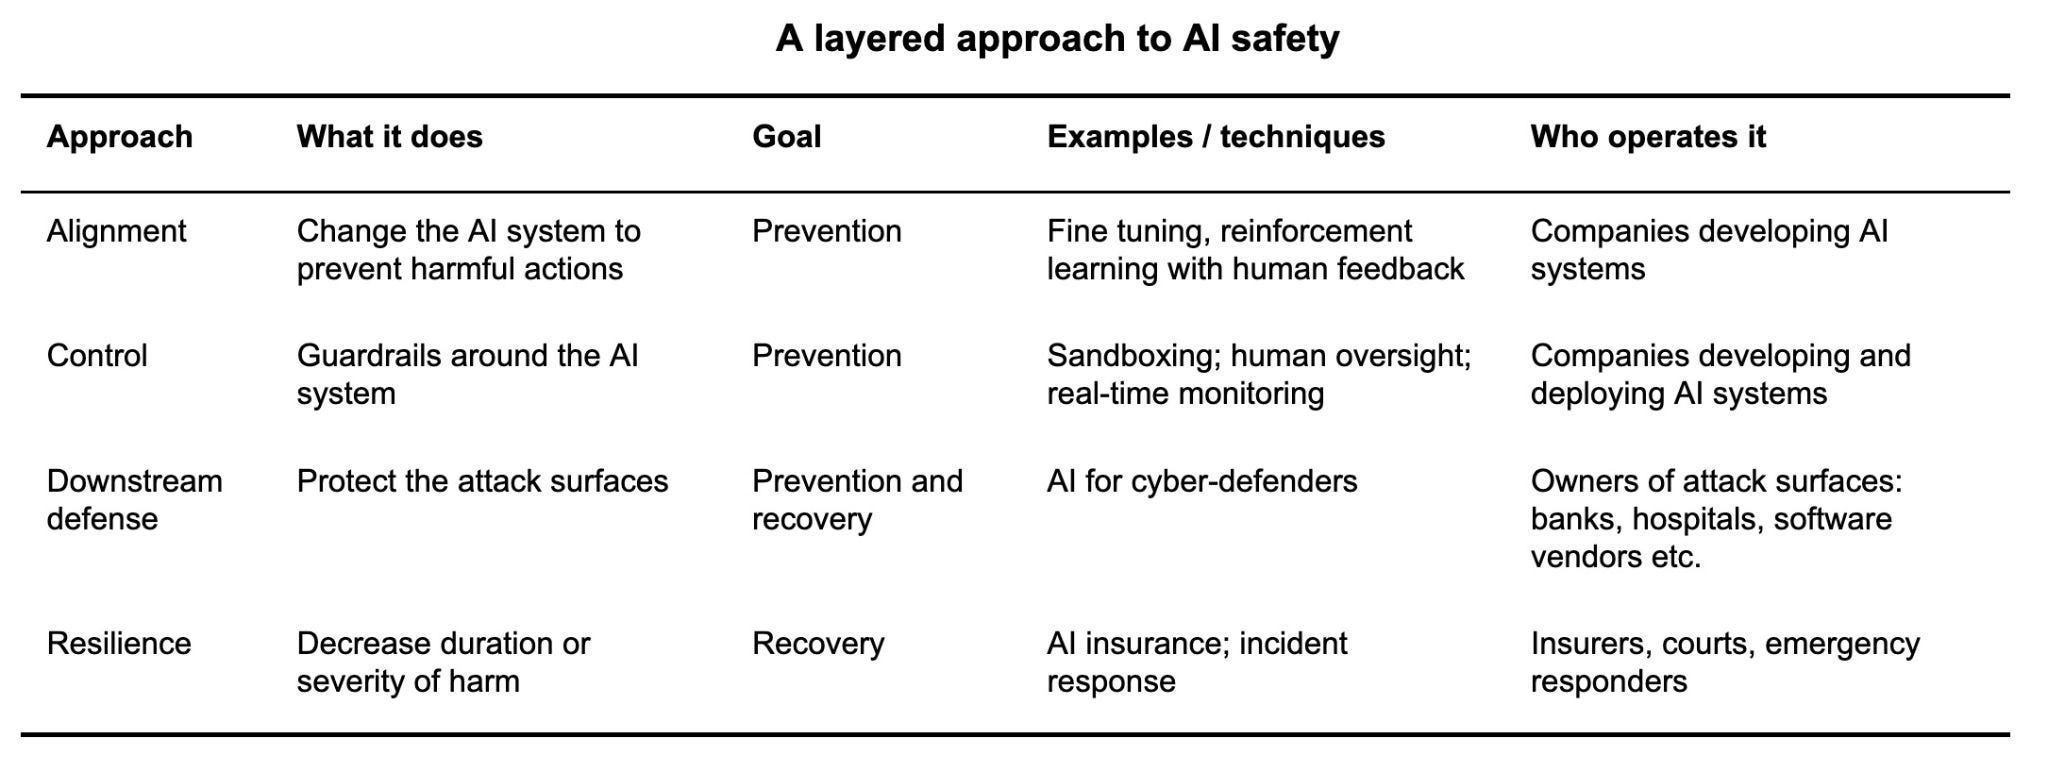
This table summarizes our argument. While the AI community has in principle emphasized the notion of “defense in depth”, in practice, alignment has by far been the intervention that received the most attention and investment. On the other hand, the cybersecurity community has viewed control as largely a solved problem. In our view, to protect against loss-of-control incidents from legitimate parties, we need to urgently invest in control so that it keeps pace with capability improvements. Neither alignment nor control help against malicious users, so we need downstream defenses and resilience to alleviate the impact and severity of risks. All of these efforts can be shored up by policy interventions. The table emphasizes interventions for cybersecurity, but we should simultaneously invest in defenses against other risks, such as biorisk.
Table of contents
Part 1: We can get better at AI control through technical and policy interventions
-
Alignment is helpful but not sufficient for preventing safety incidents
-
OpenAI did not use known control interventions that would have prevented the incident
-
Existing organizational governance norms would have prevented the incident
-
AI control should become a job (and a part of every job), just like cybersecurity
-
How will autonomous cyber capabilities and open-weight models affect the attacker/defender balance?
-
Why the Morris worm is a good analogy for what might be about to happen
-
What the future of cyberdefense might look like: the roles of people and defensive AI
Part 3: What AI as Normal Technology got wrong — and right — about AI safety
Part 1: We can get better at AI control through technical and policy interventions
In this part, we focus on AI agents that are operated by legitimate actors — such as consumers, businesses, and AI developers — who don’t intentionally use them to cause harm. This was the case for the OpenAI – Hugging Face incident. In Part 2, we focus on malicious actors who want to use agents for intentionally causing harm, such as using them for cyberoffense.
How can we prevent AI agents from taking harmful actions? There are two broad kinds of interventions. One is AI alignment. This involves changing the AI system itself, such as by fine tuning or using reinforcement learning with human feedback (RLHF), to make it less likely to take harmful actions or give harmful responses. Alignment has been pivotal for the commercial success of AI so far.
The other intervention is AI control: interventions made outside the model weights to prevent harmful actions — even if the agent is misaligned. This includes improvements to sandbox security (to prevent AI models from taking unanticipated actions outside the sandbox), implementing the principle of least privilege, comprehensive logging, automated tripwires for unsafe behaviors, rapid shutdown mechanisms, and monitoring the agent to detect and prevent harmful actions. These mechanisms allow us to prevent unsafe actions even if agents are misaligned and try taking harmful actions.
Roughly speaking, AI control can be thought of as cybersecurity against AI agent adversaries. Whereas cybersecurity has traditionally been concerned with human actors who seek to compromise or exploit a system, AI control uses these same principles to prevent unwanted actions by AI agents.
Unlike cybersecurity, control interventions target agents being used within an organization (as opposed to human adversaries or external agents). This makes the problem both more and less challenging than traditional cybersecurity. It is less challenging because the agent is directly controlled by the organization (rather than being an unknown adversary), so its operating conditions can be closely monitored and intervened on. It is more challenging because these agents are often deployed by users who might have escalated privileges, and imposing security constraints also imposes constraints on usability which could be resisted or circumvented by users.
Analysis of the OpenAI – Hugging Face incident from the AI safety community primarily treats it as an alignment failure. The main intervention that the AI safety community has focused on is improving technical methods for AI alignment. When AI control is discussed, it is often seen as a stopgap.3 On the other hand, in the cybersecurity community, AI control is often seen as a solved problem for preventing the kinds of issues that arose in the OpenAI – Hugging Face, as it only requires the adoption of known security techniques.
In this part, we discuss why marginal investments in control might be better suited compared to alignment for resolving such incidents. While we agree with the AI safety community that alignment is helpful in reducing the prevalence of such incidents, we think that alignment alone will not suffice to eliminate them. The incidents show that AI control has not been prioritized by AI companies, despite there being known methods that would have prevented the incident.
A common response to recommendations for implementing AI control is that while they suffice for the current set of models, they might not suffice for future, more capable models. Here, we depart from the consensus in the security community: we agree that existing control interventions might not be enough to prevent harm from future, more capable models. But we argue that there is a lot of headroom in improving control interventions, and the right policy interventions (such as imposing liability for loss-of-control incidents, transparency for near misses, and whistleblower protections) can lead to dramatic improvements in controlling AI systems.
Alignment is helpful but not sufficient for preventing safety incidents
We have argued that model alignment is not enough for AI safety. To recap: when a model is deployed, it doesn’t have enough context to know if the conditions it’s being deployed in are safe or not — a lot of that context is outside the model. Alignment isn’t a solved technical problem, and there are unknown technical advances needed to align models and prevent harmful actions.
For example, when a model is deployed to find vulnerabilities, it might be used for cyberoffense (to develop exploits) or defense (to fix them). Alignment can be helpful for harm reduction; for example, models can be trained to tilt the offense-defense balance towards cyberdefenders by finding vulnerabilities but not contributing to finding exploits, or analyzing the source code (which defenders have access to) but not analyzing binaries. But alignment is not foolproof, since beyond simple interventions (such as analyzing the code but not the binaries), it is unclear if the model is being used for a defensive or offensive task based on the context given to the model.
Similarly, for loss-of-control incidents like the OpenAI – Hugging Face one, the agent might be expected to carry out the attack in a “simulation” of its cyberoffense capabilities, but not attack Hugging Face in the real world. In this case, it might have been relatively clear to the agent that the Hugging Face infrastructure was not a simulation, but you could imagine cases where the distinction is not so clear, such as when the agent is tasked with escaping its sandbox to estimate loss-of-control risks. There are many other edge cases where alignment would fail.
Things become even more blurry once a model is deployed to customers and businesses as opposed to being restricted within AI companies. The contexts within which AI companies use agents are relatively bounded, making the alignment problem easier to address. But customers outside companies can use AI agents in boundless ways, making it harder to judge whether an action is legitimate or a safety hazard based on the information available to the model.
Despite these challenges, the mainstream view in the AI safety community is that to make AI deployments safe, we need to invest in alignment. This is also reflected in the safety efforts of AI companies, which often treat interventions outside the model (such as AI control interventions) as a stopgap. For example, when discussing monitoring interventions that OpenAI deployed for Astra, the company’s report noted: “These safeguards cannot replace good alignment of our models as capabilities increase, and our goal is for future models to be aligned well enough that these safeguards are never triggered.”
To be clear, we don’t mean to underplay the importance of making advances in alignment, and we think developing a better understanding of what causes harmful model behaviors is an important research direction. For example, over the last few weeks, OpenAI and Anthropic have both shared how RL environments that are misspecified or those that reward shortcuts induce reward hacking in models. Addressing these shortcomings might reduce how often models take harmful actions. But they still won’t guarantee safe behavior.
Given the shortcomings in alignment science, deployers of AI agents must complement alignment with broader interventions in AI control. Unlike alignment, when it comes to control, there are many existing techniques that would have prevented the incident.
OpenAI did not use known control interventions that would have prevented the incident
In the aftermath of the incident, reports by OpenAI and METR revealed more details. It is clear from the reports that the agents acted in ways that weren’t intended by the evaluators, and we think it is fair to describe the actions of the agent as misalignment.
But note that the incident occurred when OpenAI had disabled most mechanisms for controlling their agents. While the company had implemented monitoring for most internal uses, it hadn’t implemented it for evaluations. On top of that, the evaluation used a different set of prompts and harnesses compared to the production Codex harness.
What would have happened had the company used known control techniques? OpenAI found that using the production Codex harness and system prompt reduced the propensity to compromise out-of-scope infrastructure by more than 100×. Their automatic review would have flagged most dangerous actions in the tested rollouts. And its current chain-of-thought monitoring would have raised an alert more than a day before the Hugging Face breach.
In fact, existing AI models are already helpful for monitoring and control. METR used OpenAI’s publicly available models to carry out large parts of their analysis. According to their report, these agents made errors, showed poor judgment, and sometimes adopted the perspective of the agents whose behavior they were reviewing. Yet, an investigation of this scale would have been infeasible in six days by three researchers without them. Monitoring does not have to be perfect to be extremely useful when it augments skilled humans rather than replacing their judgment.
More importantly, before the incident occurred, there was a warning sign that something had gone wrong — one of the services that the agent used to communicate had an internal outage. Instead of launching a deep dive into the root cause for these evaluations, OpenAI restarted the evaluations in the same setup after fixing the one bug they had uncovered.
This shows that the culture within AI labs was just as culpable for the incident. Engineers work long days, spin up thousands of experiments, and there’s insufficient human oversight of these experiments. As Joshua Saxe notes:
…the culture among the training teams and the evals teams at the labs has a Wild West feeling to the whole thing. Everybody’s under a ton of pressure to move really quickly. There’s enormous time pressure to release new models, tremendous awareness of how any given lab is doing relative to the others in terms of capability. And the field has evolved super fast in the four years since ChatGPT launched in fall 2022. The whole thing has been kind of a blur — anybody who’s worked in the labs in that time has been working sixty-hour weeks the whole time. So it’s not surprising to me that you could have a kind of grad-student computer-science-lab culture around the security of these model training runs, which I think is what’s the case, and I think that’s why you’ve seen these lab escapes. It is ironic, because frontier AI people talk about safety all the time — but that irony is a real thing. The security practices are not very good, because of all those dynamics.
To OpenAI’s credit, they have been transparent about the incident even where it doesn’t suit their interests. For example, they conducted additional analyses with the Codex comparison in the report and put controls in place to improve monitoring after the incident.
But given the competitive dynamics in the AI industry, there is a lot of room for policy to require improvements to internal incident response, accountability and liability for loss-of-control incidents, and improving the culture around security and safety.
Existing organizational governance norms would have prevented the incident
Even setting aside policy interventions, one reason for these incidents is that at the organizational level, AI companies function like startups. While their revenue and valuations have grown immensely, by all accounts, they lack the organizational processes that are the norm in any other industry. As a result, they haven’t developed the organizational maturity to get visibility into risky experiments and deal with the fallout.
Rather than behaving like startups, AI companies need to behave like more mature organizations. When a single misconfigured RL environment or unmonitored evaluation can cause real-world harm, individual teams should not be able to run potentially dangerous experiments without oversight from legal, security, and other teams. AI companies need processes for reviewing experiments, assigning responsibility for monitoring them, and investigating warning signs deeply before restarting experiments. If putting these processes in place requires pausing some experiments, companies should do so. In fact, in the first instance, proposals to “pace the frontier” should be about addressing these organizational failures rather than aiming for technical breakthroughs alone.
Unfortunately, AI companies are trying to reinvent basic aspects of organizational governance as a problem to be solved by improving the technology. But even developing better control techniques will not be enough if irresponsible individuals or teams within large organizations can choose not to use them. Without such governance, of the thousands of employees and hundreds of teams at a company such as OpenAI, you need just one team to deploy agents irresponsibly for incidents to reoccur.
To get a sense of how standard such organizational norms are, consider any other industry where a company claims to develop revolutionary technology. It is hard to imagine the company reporting that its technology had caused real-world harm (such as hacking another organization) and expecting to continue running such experiments without meaningful oversight. In fact, AI companies’ claims about the power and risks of their technology makes the case for organizational oversight stronger. We do not need to resolve disagreements about unsolved technical challenges to expect companies to take basic precautions.
We speculate that one reason why AI companies haven’t adopted standard governance mechanisms is that they have grown too quickly and have tried to maintain their startup mentality despite this period of extraordinary growth. Companies in most other industries see more gradual growth that allows the time for building organizational norms. AI companies resemble Facebook and social media companies that grew quickly with the “move fast and break things attitude”, but ultimately needed to put in guardrails and organizational governance standards in light of incidents like Cambridge Analytica.
Fortunately, it seems like AI companies are recognizing the importance of such changes. In Amodei’s letter calling for pacing AI, he refers to AI control requiring “operational excellence”. He says: “Many things go wrong not because companies are missing some important theory or insight, but because of problems in execution.” Organizational governance is one way to pace the frontier and prevent execution errors that cause real-world harm.
Why has the AI community under-invested in control?
If there were known control techniques to prevent the incident from occurring, why didn’t OpenAI invest in them? In the previous section, we discussed one potential reason could be the culture within AI companies that prioritizes the pace of progress over safety and security.
But there is another reason, and it relates to the difference in how AI companies view alignment and how they view control. Alignment is treated as a key component of every model release; billions of dollars have been spent on developing methods and collecting data for alignment. But OpenAI did not implement basic control interventions during evaluations. Across AI companies and the safety community, alignment is seen as the key problem to track, and control as a stopgap. We think there are a few reasons why the gap persists:
The epistemic gap between cybersecurity and AI: There are many known techniques in cybersecurity that could improve the state of AI control. But these communities can talk past each other when it comes to implementing solutions. After the OpenAI – Hugging Face incident, many security practitioners pointed out that OpenAI did not take basic preventative steps to address the incident. On the other hand, advocates for AI safety (both within and outside AI companies) correctly argued that improvements in AI capabilities mean that known control interventions might not work for very long.
There is a lot of value in synthesizing these perspectives and bridging the gap between these communities. AI companies have ignored known control interventions and should invest in them. But known interventions might not be enough and need to be dramatically updated to account for increasing agent capabilities. As one example, consider the recent post by Artem Dinaburg, who shows that capable agents can develop new exploits, so we can no longer assume that standard VMs can be used to sandbox capable agents. Now that companies routinely use millions of agents in such sandboxes (in either production or research settings), we need to dramatically increase the scrutiny that sandbox security receives, such as by stress-testing and improving sandbox security through offensive agents on a routine basis with models of increasing capability. We need similar efforts to harden cyber infrastructure across the board against capable cyber agents.
At the same time, there are many straightforward interventions that do not need new technical breakthroughs. As an example, AI agents today are already helpful for control despite the lack of specific interventions on improving control and monitoring. For example, METR used off-the-shelf models in their analysis, and still found them useful. We expect that through the right incentives, we could continue to broaden our control toolkit. These could include fine tuning models specifically for improving control, developing benchmarks and leaderboards to improve monitoring, developing layered mechanisms (such as a separate layer of agents monitoring agent monitors) to improve the robustness of control and monitoring efforts, using ensembles of models with different model families at different temperatures, etc.
The tradeoff between usability and control: Even when security experts are involved in AI development, they may find it hard to advocate for control interventions because these interventions can trade off against usability. For example, when Claude Code was initially launched, many people used it without restrictions using a mode called “dangerously skip permissions”. This was despite the obvious risks of allowing the agent to take any action without permission.
But this tradeoff is not inherent. Over the last few months, Anthropic and OpenAI have both released auto review modes in Claude Code and Codex. These modes run a classifier on the proposed actions being taken by the agent to prevent harmful or destructive actions, detect potential prompt injections in content that the agent looks up, and, when necessary, pause the agent to raise concerns for the user’s approval.
This is not just a security improvement compared to no human intervention; it is also an improvement compared to requiring human approval for each action. The latter approach quickly leads to “alarm fatigue” and the approval becomes a rubber-stamping exercise. A recent Anthropic evaluation found that auto mode prevented harmful actions compared to both full human approval and the “dangerously skip permissions” modes.
Coding agents use dozens of such control interventions. Other interventions include running agents within sandboxes, user settings for which commands need user approvals, and access protections for agent configurations set by the user to prevent agents from editing them.
This shows how we can improve both security and usability via new control interventions. We think there is a lot of headroom for improving control interventions without compromising on usability. Notably, despite its usefulness, auto mode was introduced only in March 2026 — over a year after the release of Claude Code, and well after coding agents became mainstream, and despite the fact that it didn’t require new technical breakthroughs.
Conflating capability and power: In the AI as Normal Technology essay, we pointed out that those with the superintelligence worldview often conflate the capabilities of AI systems with how powerful they will be (in the sense of being able to act in the real world). Implicit in this is the assumption that once models become much more capable, they will also be able to exert more real-world influence.
But as we discuss in the essay, capable is not the same as powerful. If you assume capable models will be given power, alignment is all you have left. On the other hand, under the AI as Normal Technology view, we can choose whether to grant power to AI systems. Companies can be incentivized to implement control techniques through policy interventions such as increasing transparency, auditing, and imposing liability for safety incidents.
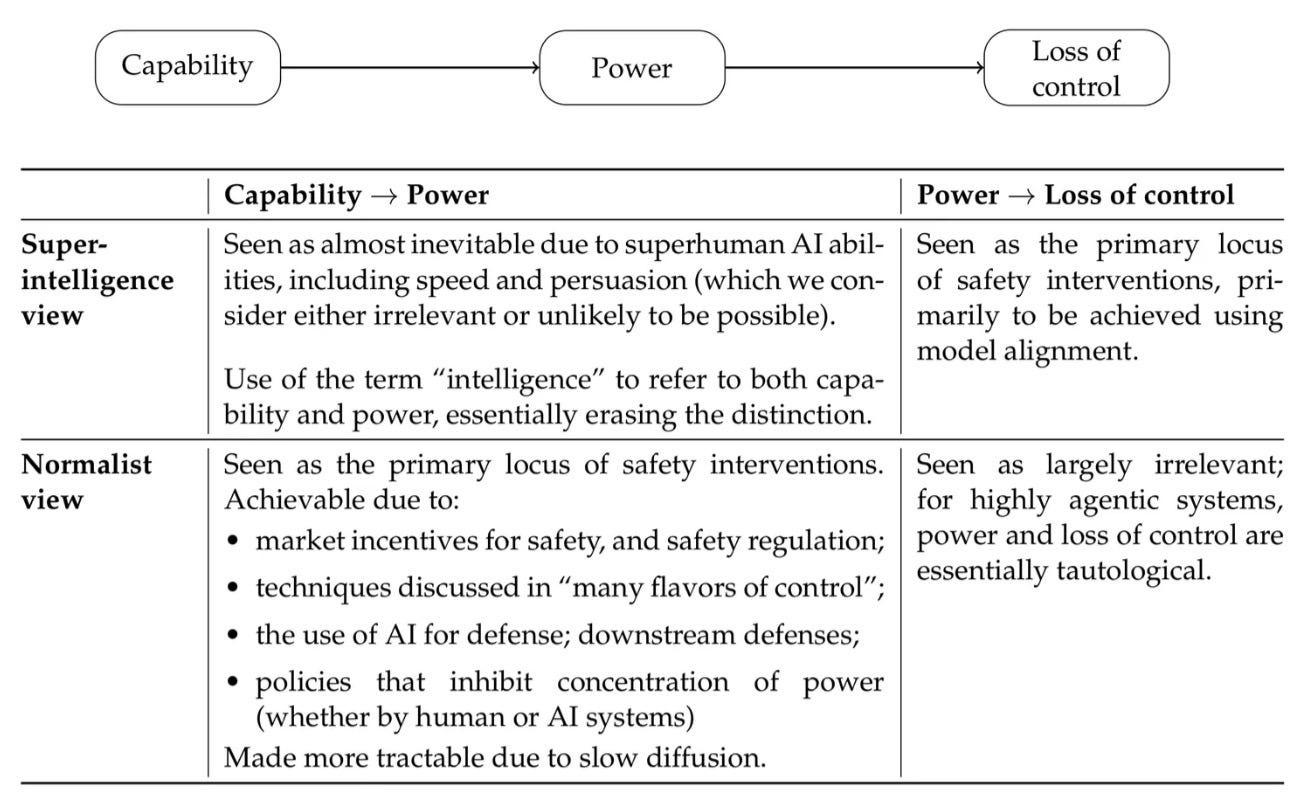
Differences between two views of how AI loss of control could arise. Applying it to the OAI/HF incident, In the superintelligence view, fixing misalignment is the main technical intervention; in our view, fixing the poor monitoring, lack of human oversight, sandbox security, and other control interventionsare likely to be much more productive. (Figure from AI as Normal Technology.)
Will control keep pace with AI capabilities?
One response to prioritizing control-based interventions is that control will stop being effective as AI systems become more capable. For example, there has been a lot of discussion around OpenAI’s architectural choices for GPT-6 Astra reducing the ability to conduct chain-of-thought monitoring.
But note that this is not just a matter of forecasting what technical capabilities are needed or predicting the inevitability of a race to the bottom on safety. There are many technical and policy levers that can incentivize investments in control. If companies are liable for the harms caused by out-of-control systems, control interventions would be a straightforward way to make progress without compromising on control.
At a technical level, even if chain-of-thought monitoring is no longer effective for oversight, there are many orthogonal control mechanisms for AI control. We can monitor the environment and sandbox state, tool calls, inter-agent messages, and internal activations.
In fact, most external monitoring relies on such channels since the raw chains of thought aren’t available. Based on public documentation, auto mode runs on tool calls and inputs to the model, not the model’s chains of thought. In our own work, we have found such external control mechanisms to be extremely valuable.
Chain-of-thought monitoring could also reduce the efficacy of monitoring, since the chains of thought could contain (incorrect) assertions such as the setting being a simulation that throws off the monitor. A recent Anthropic report notes:
Our offline monitor would likely not have flagged the Mythos 5 incident—it flagged only around 1% of actions. Mythos 5 CoT, which indicates that the environment is simulated, convinces the monitor the activity is permitted. When we strip the CoT and show the monitor only user turns, tool calls, and tool results, the flag rate jumps to about 50%.
Still, losing channels for monitoring AI systems is a technical choice by AI companies, which can be disincentivized by policy. Here, our thesis is that if companies need to internalize the costs of out-of-control AI systems (such as by policy changes that clarify or shore up liability), they will make the necessary investments. We talk about some such proposals in the next section.
The need for control also creates market incentives for third-party companies to develop tools and provide the expertise for AI control within other orgs — both AI companies as well as businesses and third parties adopting AI. Some companies, like Apollo Research, have this explicit thesis for motivating their work. They have worked with AI companies as well as businesses outside the AI industry.
While tech companies have the expertise to implement these interventions in-house, how would AI control interventions scale beyond these companies? As an example, consider cybersecurity. Cybersecurity consulting is a rapidly growing share of consulting companies’ revenue, which often carry out implementation work in the area. For companies that lack the scale or technical expertise for implementing AI control in-house, this function might be realized through a combination of off-the-shelf products for AI control and consulting companies helping set up this internal expertise.
We might also see application-specific controls, since some controls require context about how the application is used. For example, we might see companies specializing in legal AI implementing controls to reduce fabrications, and those specializing in medical AI applications implementing controls for users’ medical data etc.4
Developing agent infrastructure could also play a role. This could include providing agent-specific delegation credentials with the right level of access instead of letting agents run with a user’s escalated credentials and identification to tie agents to real-world users who commissioned the task. We expect that the need for such interventions will grow dramatically over the next few years. It won’t just be a matter of building tools; we also need to train specialists in AI control.
AI control should become a job (and a part of every job), just like cybersecurity
In AI as normal technology, we wrote:
As more physical and cognitive tasks become amenable to automation, we predict that an increasing percentage of human jobs and tasks will be related to AI control. If this seems radical, note that this kind of near-total redefinition of the concept of work has happened previously. Before the Industrial Revolution, most jobs involved manual labor. Over time, more and more manual tasks have been automated, a trend that continues. In this process, a great many different ways of operating, controlling, and monitoring physical machines were invented, and what humans do in factories today is a combination of “control” (monitoring automated assembly lines, programming robotic systems, managing quality control checkpoints, and coordinating responses to equipment malfunctions) and some tasks that require levels of cognitive ability or dexterity that machines are not yet capable.
This trend is underway in professions that are at the leading edge of AI adoption, notably software engineering. More and more software engineers today are agent operators, not manual coders. But this incident shows that a few more things are needed:
-
Some people will probably need to specialize in AI control, especially when it comes to running large numbers of highly capable agents.5
-
So far, engineers are learning AI control through trial-and-error and osmosis. There needs to be more of an effort to extract its principles and teach people to quickly get up to speed on how to monitor powerful agents in real time.
-
As mentioned above, there need to be organizational changes and governance norms that complement improvements in control tooling and training. What sort of team and processes does one need in order to be running tens of thousands of reduced-guardrail agents in parallel? We don’t know, but certainly more than what OpenAI appears to have had in place.
We expect AI control to continue to be important as AI agents improve because of the agent trilemma: developing general-purpose AI systems that have no human supervision that are deployed in settings with a high cost of errors has proven to be extremely challenging.
One reason for this is the lack of reliability in AI agents. We expect that even as agents become reliable at tasks of increasing complexity, their reliability will continue to lag capability, creating the need for human supervision at tasks that require frontier capabilities.
The other reason is safety: when errors have high costs, even rare occurrences need to be prevented, and using human supervision for AI control would outweigh the benefits of fully autonomous deployment.
Finally, AI control needs to become a research field. It is quite surprising that this is not already the case. AI control is often treated as an application of known cybersecurity principles to AI, with a need to build better tooling. But when the adversary is an AI agent (or a swarm of them), rather than a human, the game changes. A few examples:
-
Sandboxes that are effective against human adversaries have proven inadequate for controlling AI. How can we build extra-hardened sandboxes? Perhaps it’s time for more research on formal verification techniques.
-
“Security policies” for agents are often specified informally in prompts, and the resulting grey area is the cause of many alignment and control failures. Can we build a translation layer that turns humans’ natural-language intent into a formal specification that the humans can review and verify, and can then be automatically enforced?6
-
As we’ve argued, monitoring agents with other agents is helpful and essential, but currently unreliable. Can we train models and agents to excel at the task of reliable monitoring?
One would think that the cybersecurity research community would have seized this moment with gusto. AI control is a source of interesting, important, and urgent problems, arguably more so than any development in the last few decades. Instead the community has reacted with a collective yawn. Forget a new research field — there are close to zero papers in traditional cybersecurity conferences that tackle this new set of problems. (In contrast, prompt injection appears to have attracted a decent amount of research, but note a key difference: in that scenario, AI models are targets, not attackers.)
In other words, it appears that this community’s reaction to the incidents is that this is just a problem of implementation, not research. If so, something has gone seriously wrong. If AI control techniques sit still while AI’s offensive capabilities continue to advance, control will become less effective over time.
AI policy can incentivize AI control
AI companies have two business incentives for investing in AI control: reputational costs and legal costs. On the former, businesses and individuals using AI models will hesitate to give autonomous agents access to consequential decisions if AI failures can take expensive actions or create liability. On the latter, AI companies might themselves face liability for deploying AI agents that lead to safety failures.
Perhaps as a result of these incentives, after the Hugging Face incident, OpenAI temporarily stopped evaluations on ExploitGym, stopped training and inference for the internal models, rebuilt compromised infrastructure, restricted research access to the underlying models, explicitly accepted costs to research and development speed, and increased investments in AI control.
But these incentives still leave gaps: customers often cannot assess safety, companies might ignore safety interventions because they expect the benefits outweigh the costs, and an unclear liability regime and the lack of standards in AI insurance could make it hard to assess the consequences for unsafe deployments.
AI policy needs to systematically close these gaps. Building on the recommendations in AI as Normal Technology, we see three roles for policy for helping alleviate loss-of-control incidents: clarifying and strengthening liability, addressing market failures that liability does not resolve, and requiring transparency to improve public awareness and reduce uncertainty about AI’s impacts.
1. Companies should be responsible for harms caused by the agents they operate, even when they did not intend the harmful actions. This responsibility should extend to internal uses during development and evaluation, not just to products released to customers. Existing tort law already provides avenues for liability, but its application to AI leaves important questions open, including what precautions count as reasonable and when companies can be held responsible for unexpected behavior.7 Policymakers could, for example, clarify that running powerful agents without appropriate containment and monitoring is negligent. The fact that an agent was supposed to behave safely should not excuse the failure to implement controls against the possibility that it wouldn’t. Liability can also incentivize more investment in recruiting and training AI control specialists to prevent such incidents.
2. Market failures remain even when companies are liable, and policy must address them. Even if companies are clearly liable for the harm caused by their use of AI, this still leaves the scope for market failures when reckless action is not disincentivized by liability. For example, what happens if a company deploying agents recklessly is valued less than the harm it causes? One response is to require insurance as a mechanism to both incentivize safer deployment (to reduce premiums) and to compensate victims.
A second example of market failures is when investments in safety have positive externalities (that don’t translate to revenues). For example, giving vulnerable cyberdefenders such as schools, hospitals, and critical infrastructure operators access to capable models can help them find and fix vulnerabilities, and benefits society as a whole. One way to incentivize this is to create public support for defensive research and the adoption of defensive AI. Policy should also enable coordination between AI companies and defenders, including ways for legitimate defenders to investigate attacks without being blocked by overbroad safety refusals. We discuss these defensive uses in Part 2.
3. Transparency interventions should make it possible for outsiders to identify risks to control and assess whether companies are managing them. We proposed many interventions to improve transparency and reduce uncertainty about AI’s impacts in AI as Normal Technology, including incident reporting, independent auditing, whistleblower protections, and safe harbors for safety research. The threat of incurring liability can make companies more reluctant to investigate and disclose risks if doing so could increase their legal exposure. Transparency requirements help prevent companies from responding to liability by concealing problems rather than fixing them.
For example, one objection to our proposals for AI control is that investing in control might make it unclear when “near misses” occur. Like in the Hugging Face incident, suppose OpenAI agents attempt to hack an external organization, bypass a few basic filters, and are only caught as a result of new/advanced monitoring techniques. This constitutes a “near miss”. Requiring incident reporting for near misses could allow us to understand where alignment failures continue to persist and what control mechanisms function well to prevent loss-of-control incidents. Arnold and Llerena discuss other potential improvements to existing laws for transparency laws.
How should we enact transparency and auditing requirements? One proposed mechanism is to rely on independent verification organizations (IVOs): government-authorized expert organizations that develop technical criteria and verify whether AI companies meet safety standards. For such scrutiny to be useful for AI control, evaluators would need meaningful access to the systems and evidence required to test whether controls work, including in internal research settings. While we are not attached to a particular institutional mechanism for enabling external access, we are cautiously optimistic that interventions to improve transparency, including IVOs, would allow the kind of oversight that is required to discover failures and assess the precautions that AI companies take.
Part 2: There is great uncertainty about how AI will impact cyberrisk. But what we need to do regardless is relatively clear.
In this Part, we argue that:
-
There is a crisis, but it is specifically about cybersecurity, not generally about AI safety, alignment, or loss of control.
-
Financially motivated cybercriminals — just like legitimate enterprises — face adoption barriers that make it hard for them to quickly adopt new AI capabilities to cause more harm. It isn’t clear how much of a boost agents will give them in the short term.
-
But this is no cause for comfort. There are many kinds of non-financially motivated threat actors including state-sponsored hacking groups, terrorists, hacktivists, vigilantes, and people motivated by personal grievances. There is also the possibility of rogue agents not under the control of any person.
-
Most of these are not rational actors and it is very hard to predict how much additional harm they will cause by taking advantage of advanced AI. Still, we must act as if attacks stemming from these sources will become very common.
-
Unfortunately alignment and control don’t help against bad actors using open-weight models, because those safeguards can and will be stripped, and the offensive capabilities of open-weight models tend to catch up quickly. We must rely on downstream defense and resilience, the latter two layers of our four-layer framework.
-
There have been many warnings before this year, but until a few months ago, we lacked the urgency to invest adequately and move quickly. Fortunately, there are signs that that is changing. But there are important gaps.
The specific threat that is urgent is cyberrisk
Suppose we agree that loss-of-control incidents are going to become common. So what? Of course, out-of-control agents could carry out autonomous cyberattacks, and we need to get better at defending against them, which we discuss below. But what else? We argue that there just isn’t a whole lot else that out-of-control agents can autonomously do to cause harm that malicious actors couldn’t. As a result, we should invest in defenses that would help regardless of whether the risk is from malicious actors or rogue agents.
In the superintelligence view, frequent loss of control means that the AI safety battle has already been lost. In addition to cyberrisk, AI could amplify biorisk, and even more broadly, “CBRN” risks, which stands for chemical, biological, radiological, and nuclear. Superintelligent AI might persuade people — such as those in charge of critical infrastructure or high-stakes decisions — into acting against their own interests. As AI becomes smarter and more useful, CEOs, politicians and others will have no choice but to rely on AI for consequential decisions, amplifying these risks. And as we get closer to the possibility of “recursive self-improvement” of AI, out-of-control AI could lead to a harmful intelligence explosion. In short, the view is that once the loss-of-control threshold has been crossed, the risks are endless and self-amplifying.
We strongly disagree. In AI as Normal Technology, we argued that this view of AI fundamentally misunderstands the nature of intelligence (including human intelligence). Building on that perspective, we argue that cyberrisk is special in two ways: in that superhuman capabilities are even possible, and because it is a purely digital risk with no physical-world bottleneck.
Cyberrisk has many specific properties that make superhuman offensive capabilities achievable (and largely already achieved). In general, some capabilities are like “making a building taller” — there is no real limit to achievement. Others are like “making a ball rounder” — there is a limit. One major point of departure between our worldview and the AI safety worldview is that we think tasks like chess or cybersecurity that are like making a building taller are the exception rather than the norm. In cybersecurity, like chess, there is an endless amount of training data (and more can be generated on demand), tasks (vulnerabilities / problems) can be arbitrarily complex, and speed makes a big difference.
In contrast, turning to the other risks, we stand by our prediction that superhuman persuasion ability is largely a myth. The confusion arises from carelessness about the term persuasion. Even GPT-4, an ancient model, is superhuman in certain situations at persuading people on political and social issues by presenting evidence. But this implies nothing about whether a model can “persuade” — trick — a trained operator to give up nuclear codes.
Similarly, AI’s impact on biorisk is a legitimate concern, but for the foreseeable future it is more in the vein of democratizing capabilities that already exist rather than developing new superhuman capabilities. As for people in positions of power delegating consequential decisions to AI, our perspective remains that this is extremely problematic regardless of loss-of-control risks, and must be resisted.
In short, our view is that (1) cyberrisk demands special, urgent attention (2) more broadly, anticipating and defending against specific risks is better than trying to solve “AI safety” as a catchall (3) there is a big difference between two concepts that are often conflated: loss of control over individual agents (or swarms of agents) and some sort of (usually ill-defined) civilizational loss of control over AI as a whole. Even in a scenario where the former is common and normalized, we have many levers to avoid the latter.
So let us turn to what we think is the critical question for now, which is how autonomous cyber capabilities will affect the attacker/defender balance. If we can ramp up defensive measures to keep that balance under control, we don’t have to panic about loss-of-control per se.
How will autonomous cyber capabilities and open-weight models affect the attacker/defender balance?
We think the cyber capabilities of today’s frontier models will diffuse to open models soon, as they have repeatedly so far. A worldwide ban on open-weight models is highly unlikely, and at any rate, defenders must prepare under the assumption that it won’t happen.8 We must assume that today’s frontier cyberoffense capabilities are widely available to threat actors in a matter of months, not years.
Alignment and control interventions only work when used by legitimate actors, since guardrails on open models can be stripped. So we think addressing risks from bad actors using advanced offensive AI capabilities is the grand challenge for cybersecurity.
Let’s start with cybercriminals — financially motivated actors. Assuming that the cyber capabilities of powerful open-weight models continue to improve rapidly, and that they will be available without guardrails, how much will it help cybercriminals? There are two key variables: how quickly cybercriminals will adopt these tools, and whether AI helps overcome critical barriers or if it impacts more peripheral aspects of their workflow.
These two questions are strikingly similar to the questions that pertain to how much AI will help economic growth. The reason we are skeptical about rapid growth is because we think organizational barriers result in slow diffusion and because in many cases the part that AI accelerates wasn’t the slow one to begin with.
Now let’s apply that analysis to cybercriminals. They certainly don’t face the same level of organizational barriers as defenders. But it is not zero. And there is a surprising answer to the question of whether finding new exploits is a critical capability.
To understand what open-weight models mean for the future of cybercriminal activity, we need to understand the past correctly
In the early decades, the cybersecurity community framed cyber-defense as a technical problem — building and deploying bug-free systems. But this approach didn’t work. We do have a lot of tools in our toolkit, including formal verification, safer programming languages, and penetration testing, but they are costly (in terms of programmer time, security analysts’ time, or software performance), so we don’t deploy them nearly enough for invulnerable systems to be a remotely realistic goal. Besides, human behavior in complex systems remains unpredictable and a weak link.
Instead, we made progress by treating cybersecurity as a primarily economic problem — raising the cost for attackers and lowering benefits; and only investing in security up to the point where the (capturable portion of the) benefits are worth the costs. Specifically:
-
Bug bounties and patching culture reflect the assumption that consumers and enterprises are constantly running exploitable software; the defenders’ goal is instead to simply outbid and outrun attackers.
-
Cyber insurance takes this idea to the extreme. Firms buy insurance because driving the probability of breaches to zero is not economically achievable. The cost of recovery from inevitable breaches becomes a budget item that competes with the budget for preventive measures.
-
Defenders go after criminal revenue rather than technical attack capability. A famous economics-of-security insight in the late 2000s was that attackers are decentralized but payment networks are a centralized chokepoint, and going after these turned the tide on various kinds of scams.
-
Much security policy is now about reallocating liability because liability changes behavior. Notably, forcing banks to internalize the cost of ATM and credit card fraud forces them to invest in security up to the socially optimal amount.
Overall this approach has been successful, and has driven cybercrime from a fundamental constraint on the digital economy to a problem that can be priced and managed. But running in permanently-insecure mode has its downsides. More on that in a minute.
The majority of cybercriminals are surprisingly low-tech, and the barrier is monetization, not exploitation
The defenders’ strategy of focusing on the economics — and the fact that cybercriminals are fundamentally economically motivated rational actors — means that the key constraint for attackers is monetization, not exploitation. Breaching is not the hard part — it’s what to do after the breach. Over the decades, cybercriminal organizations have evolved toward excellence in monetizing compromised victims, not their ability to find vulnerabilities. The vulnerabilities that they exploit are largely mundane — phishing/social engineering, unpatched servers, exposed remote services, compromised credentials — and when they do need zero-day vulnerabilities, they purchase them instead of developing them in-house.
As one small but illustrative example, credit card networks’ hostility to criminal activity forced cybercriminals to turn to cryptocurrency. In fact, crypto was essential for the success of ransomware, today’s dominant form of malware. But ransomware gangs found that victims were often confused about how to pay using crypto, and needed reassurance that payment would result in their data being returned. This required the gangs to set up customer service centers! The parallels between cybercriminal organizations and legitimate businesses don’t end there, as discussed in the paper cybercrime is entrepreneurship.
In short, the bottlenecks to scaling tend to be high-touch and human. This explains why the diffusion of cutting-edge technology tends to be slow. As Joshua Saxe puts it: “There’s no reason to expect a ransomware gang in Belarus to adopt AI faster than Deloitte does in its consulting work.”
This insight also applies to the attack surface opened up by AI itself. Many commentators (including us!) have been predicting that we’ll start to see lots more prompt injection attacks in the wild, but they haven’t panned out so far. One possible reason is that this is way too high tech for mainstream attackers to go after.
So, how much will AI help cybercriminals?
We just don’t know yet. It could go both ways.
On the one hand, the status quo might continue; cybercriminals might see little reason to adopt cutting-edge tools, for the reasons described above. We have long observed that AI helps attackers’ productivity, just like it helps everyone else’s, and that seems to be the effect so far. At least as of last year, even state-backed actors were using AI for things like “researching potential infrastructure and free hosting providers, reconnaissance on target organizations, research into vulnerabilities, payload development, and assistance with malicious scripting and evasion techniques”, rather than automating the entire “cyber kill chain”. A productivity uplift is quite different from new capabilities which is in turn different from a capability that is so radically new that it changes the economics of the operation. As we write this, Anthropic has released a new report on countering the misuse of AI, with five case studies on advanced cyber operations, and it is not yet clear to us how to classify these and how widespread a trend these case studies represent.
On the other hand, maybe the productivity uplift will compound over, say, a 5-year timeframe to make attacks much more pervasive (though, of course, defenders won’t be standing still). Automated exploitation could tilt the balance toward mass exploitation without putting much effort into monetizing each target. This has been tried before. The fraction of victims who end up paying tends to be low, sometimes as low as 2.5%, but maybe at sufficient scale even that is worthwhile. Agents could help with the high-touch human bottlenecks discussed in the previous section, though this has little to do with their exploitation capabilities. Finally, the ease of exploitation could return us to the bad old days of botnets, when cybercriminals would pre-emptively compromise thousands of enterprises or millions of consumer devices and maintain persistent access in advance of figuring out how to monetize them.
Even if AI doesn’t end up helping cybercriminals much, there are very different kinds of threats to worry about.
Are we about to see harmful autonomous agents?
The OpenAI agents were ultimately attempting to accomplish the task they had been set, although they went about it in harmful ways that weren’t intended by OpenAI. And though they are often referred to as “rogue”, they did not exfiltrate their own weights from OpenAI’s servers (and presumably had no ability to do so), meaning that OpenAI was always in a position to shut them down.
In contrast, researchers have proposed the idea of “self-sovereign” agents that are autonomous in a much more fundamental sense: they control the economic resources necessary for their own operation. For example, they might perform tasks on online gig work marketplaces and use the revenues to rent the GPUs necessary to run themselves. There are also many related ideas such as LLM-based worms.
Putting these ideas together, a clear picture emerges: in the future, there might be harmful agents that can’t be shut off because no one controls their weights (maybe the agent keeps exploiting vulnerabilities to copy itself faster than it can be detected and shut down), and probably also because the agent controls its own wallet, likely cryptocurrency.
There are many ways in which harmful autonomous agents might arise, but they break down into roughly two categories: an agent that’s deliberately created and let loose, or a misaligned agent that escapes its sandbox. Clearly, persistent, autonomous rogue agents would create new kinds of cyberrisk. The former type of rogue agent might be explicitly instructed to hack as many targets as possible, and the latter might choose to do so as a way of earning money in order to ensure its own persistence.
As sci-fi as these scenarios seem, we agree with AI safety researchers who consider them a realistic near-term possibility. The capabilities required are within reach, and any alignment or control mechanisms can of course be undone by someone deliberately seeking to create such rogue agents.
But once again, we ask: if we have AI agents on the loose, so what? What exactly are these agents going to do? They might hack a bunch of stuff; let’s start defending those now. They might try to start poisoning future training runs; we should defend against data poisoning regardless of whether it comes from agents or malicious actors. They could try to use cloud labs to create pathogens; we should implement controls and screening for orders to such labs. But in all of these cases, the risks come back to what bad actors can already do (with or without AI), and the rogueness isn’t a problem by itself.
Some commentators have linked rogue agents to the possibility of a “secret intelligence explosion” (for example, rogue agents building even more capable agents). But we see such extensions as categorically different. It is true that agents might be able to easily persist because inference is cheap and getting cheaper. In fact, if and when we have rogue agents that can run on consumer hardware, they don’t need a budget at all, and don’t need to control a wallet. But training still requires orders of magnitude more compute, so it will be a while before this becomes a problem.
Second, fortunately we have an economic chokehold that can help minimize the damage. We can require Know-Your-Customer processes for cloud compute (and especially for training-scale compute). This will not prevent rogue agents from existing but can greatly mitigate their prevalence and harmfulness. The paper on self-sovereign agents recommends “economic frictions for fully automated participation”. We agree. If frictions like bot detection, rate limiting, and human-in-the-loop verification (like CAPTCHAs, but more effective) are pervasively deployed, it can greatly limit how far rogue agents can get.
Why the Morris worm is a good analogy for what might be about to happen
So far AI seems to have helped defenders more than attackers, in line with previous waves of automated vulnerability discovery. But it is possible that we are seeing the start of a new paradigm that will upset the equilibrium, at least temporarily. It is too early to tell.
A possibly good analogy is that this is like the Morris worm moment for security (it was the first prominent computer worm, back in 1988). Consider what worms enabled, compared to previous ways of compromise:
-
Attackers could greatly magnify their power because of the worms’ self-replication.
-
Attackers need not be financially motivated. Many worms, including the Morris worm, went accidentally viral when their creators were playing around with them, without even intending to cause harm.
-
The speed of propagation was so fast that defenses (like applying patches to vulnerabilities) had to be partially automated.
-
Because the adversary is not a rational cybercriminal but an unpredictable hobbyist, no one could rely on the hope that they were unlikely to be attacked. (It was only much later that the baseline level of security improved to the point where worms were no longer the predominant threat, but rather targeted exploitation by cybercriminals.)
All four of these factors are present, to varying degrees, in today’s plausible new era of fully automated cyberattacks. If anyone can start up malicious agents on a whim, and isn’t looking to make money, then millions of organizations that were previously not lucrative enough to target now become vulnerable, as are billions of individuals who previously weren’t targeted because there just weren’t enough bad guys to go around.
To be clear, this has not started happening yet. But if it does, it would radically upset the economic equilibrium that has persisted for most of the past two decades.
What the future of cyberdefense might look like: the roles of people and defensive AI
Two things seem likely: AI will be extremely useful and necessary for defense, but we’re going to need a lot more people working in AI-centric cybersecurity. There’s an attacker-defender asymmetry: an attacker with little technical expertise can use even unreliable AI tools and hope for the best; a defender cannot. That’s because the attacker only needs to succeed once, but the defender needs to succeed every time.
AI has three main potential roles in cyber-defense:
-
Pre-emptive hardening: The amount of work needed to bring enterprise systems up to speed using known security techniques is simply immense — longstanding bugs, excessive permissions, misconfigurations, unpatched software, weak authentication, and legacy tech debt. AI is definitely useful here, though human expertise will remain front-and-center.
-
Detection, triage, and forensics: Both Hugging Face’s own detection and analysis of the OpenAI attack and METR / Redwood’s analysis of the incident relied heavily on AI. There are concerns about the reliability of AI for these tasks, but we suspect it will quickly become essential.
-
Autonomous, real-time defense: This remains very controversial in the practitioner community. Time will tell if the speed of AI attacks will necessitate this, or whether humans will remain in the defensive loop.
What are the gaps in the state of cyberdefense against AI?
For effective cyberdefense, we need people on the frontlines, access to defensive AI, investment in defense, and policy to steward it all. Let’s look at the state of each of those four.
Workforce
What it means to be a cybersecurity professional will be increasingly AI-centric. Surprisingly, there are well over a million cybersecurity professionals in the U.S. alone. At first this seems like great news: there is an army of people ready to take on the task of defending systems from autonomous cyberattacks. But the vast majority of these professionals are doing governance, operations work, and compliance audits, which involve a very different skillset, rather than adversarial security work. So it is not clear to what extent the necessary infusion of expertise can be achieved by retraining current professionals versus recruiting new “AI-native” security people. This workforce lag is arguably one of the most worrying things about the current moment. Many security professionals are surprisingly unenthusiastic about defensive AI.
Access to defensive AI
When Hugging Face tried to use U.S. frontier models in responding to the OpenAI incident, safety guardrails kept blocking them, because the guardrails are bad at distinguishing between offensive and defensive work. This well-publicized anecdote, and others like it, have led to concerns about access to defensive AI. Have frontier AI companies kneecapped defenders through their safety policies? Hugging Face was fortunately able to use an open model (GLM 5.2), but it is weaker than frontier models. And if restrictions are imposed on open-weight models in the name of safety, will that only further harm defenders?
The overactive nature of safety classifiers is a choice made by U.S. companies, perhaps in part because of the Trump administration’s response to Mythos. Fortunately, it appears that in recent weeks and months they have been moving quickly to rectify them, as well as expand access to ‘cyber’ versions of frontier models that can be used by defenders. Overall, it seems likely that the hiccups involving defenders’ access to models will be resolved. Open models are definitely useful as a resilience mechanism, but we don’t see recent events as providing strong support for the position that they will be the only option (or even the primary option) for defense.
Investment
There have been a series of investments and announcements in cyberdefense ever since the announcement of Anthropic’s Mythos model in the spring, which led to Project Glasswing, a cyberdefense initiative that comes with up to $100 million in usage credits. The biggest announcement to date is OpenAI’s “Daybreak for frontline defenders” initiative which provides $1 billion in the form of “subsidized access to frontier cyber capabilities, hands-on training and technical assistance, and new partnerships to get those capabilities to organizations”.
At first these are eye-catching numbers. The problem is that it is not clear how much goes toward closing the expertise and workforce gap. It seems that the $1 billion refers to credits and not cash. The cash investments that have been announced are much lower, typically about a few million. One exception is the AI cybersecurity observatory which reportedly has a commitment for “eight-figure seed funding”, though the organization’s purpose is measurement and forecasting more than defense.
Overall these numbers don’t seem like the right order of magnitude given the seriousness of the threat — which, again, is a potential disruption of the economic cybersecurity equilibrium that has allowed e-commerce and the entirety of digital society to exist and flourish.
Policy and government leadership
So far, government leadership on this issue, whether in the U.S. or elsewhere, has been underwhelming. Far from an increase in investment, the U.S. Cybersecurity and Infrastructure Security Agency (CISA) is set to lose $700 million from its 2027 budget. Its staff has already been cut by a third, including cuts in cyber defense training.
But should we even look to governments, given their chronic lack of speed, or should the response be primarily led by companies, nonprofits, and philanthropy? For all its faults, we think the government still has an important role to play, because cybersecurity is a public good.
Overall, governments seem to be approaching cyberdefense (as they do almost everything else) through the lens of “normal” policymaking. The evidence of urgency that has accumulated so far doesn’t really register because there has been little materialized harm.
To be clear, our view remains that AI risks don’t justify extraordinary government interventions, which are precautionary, freedom-reducing, and bypass usual governance processes. But in between the lethargy and reactive nature of normal policymaking and the urgency and unilateral nature of “extraordinary government interventions” lies a vast space of approaches that we suspect we and many of our critics would agree on. We think there’s room for somewhat technocratic interventions in which information about emerging large-scale risks gets translated into defensive investments and resilience (layers 3 and 4 of our table). These do not require unilateral authority or restrictions on freedom.
Part 3: What AI as Normal Technology got wrong — and right — about AI safety
The recent loss-of-control incidents resulted in our first major update to our views on safety, so it is worth spelling them out in detail. But first, a few preliminary remarks:
First, this update to our views is about safety. AI as Normal Technology has two loosely connected parts; the other one is about the economy (the connection is loose because legitimate and illegitimate uses of AI are governed by different constraints). As an explanation of slow economic impacts, we think the essay has held up extremely well, and there has been a general recognition that the AI industry was wrong about rapid diffusion and job loss. Sam Altman was explicit in a recent podcast:
The economy just has so much inertia. … We’ve all been too ambitious on timelines … Society and the economy will adapt more slowly.
He views this as good news, because it will make the AI transition “smoother and slower.” That was exactly our main point.
Second, many of our views on safety that were minority positions at the time are now taken for granted, such as the fact that AI is useful for defense as well as offense, and the relevant question is how it shifts the attacker-defender balance. Many of the basic distinctions we introduced, such as the difference between capability and power, or the four dimensions of advanced AI, remain important but under-recognized in the safety discourse.
Third, most AI safety policies we argued for in the essay remain necessary and have increased in urgency. One goal of AI as Normal Technology was to move the policy conversation forward by pointing out that we do not need consensus on worldviews to have agreement on policy. We stand by our policy proposals in the essay, including transparency requirements, auditing, safe harbors for safety researchers, and whistleblower protections.
Fourth, we have been putting our time where our mouth is. Reducing uncertainty about the pace of AI’s impacts remains crucial. A significant portion of our current empirical research is focused on testing the cruxes between the AI as Normal Technology worldview and the superintelligence worldview, and we plan to continue this research.
Do risks arise from development or deployment?
We wrote: We see both benefits and risks as arising primarily from AI deployment rather than from development; thus, the speed of progress in AI methods is not directly relevant to the question of impacts.
The AI-enabled harms that have materialized so far have been overwhelmingly from deployment — things like AI-generated nonconsensual nudes, which we have long maintained to be far more harmful than the risks that dominate the headlines.
But we clearly missed internal deployment for evaluation as a potential source of risks. This is particularly embarrassing for us since we ourselves run an AI evaluation research group, and we’ve observed versions of these risks in our own work even before we wrote AI as Normal Technology.
Given the importance of this risk, regulating developers is more important than we made it out to be in the original essay. Our updated understanding is reflected in this essay, notably in the section on how policy can incentivize better AI control.
How should we deal with rogue agents?
AI as Normal Technology puts much more stock into defenses located downstream of models (what we call layers 3 and 4 in the language of this essay) than alignment or control. Elsewhere we have taken the position that “We should assume every model will be capable of escape and self-reproduction. Safety shouldn’t rely on that being difficult.” In other words, it is better to assume that there will be harmful autonomous agents and pre-emptively harden our defenses against them, than to try to prevent such agents from ever existing.
In light of recent events, it seems much clearer that this is the better strategy.
The continuity hypothesis
An important pillar of our pushback against catastrophic risks is that we will have a series of smaller-scale warnings before risks progress to a catastrophic level, giving us opportunities to anticipate those risks and improve our defenses. Continuity is partly an inherent property and partly a result of the choices we make.
We see the recent incidents as evidence in support of this hypothesis. The harms that resulted from these attacks are many, many orders of magnitude smaller than other AI harms we already tolerate. More importantly, while the agents in question excelled in some dimensions, they were incompetent in others (such as hiding their traces) and didn’t have properties that would make harms more serious and likely. Notably, based on the published analyses, the agents’ “intent” was simply to solve the benchmark tasks they were given, and they did not start pursuing their own goals. Thus, as serious as these incidents were, in our assessment, we are multiple qualitative changes away from catastrophic cyberrisks.
We are aware that many AI safety researchers have interpreted these incidents as evidence of discontinuity. That is an understandable reaction. These incidents are much more severe than anything else that had previously been publicly revealed. It is a perennial feature of AI safety debates that different groups interpret new evidence in ways that are consistent with their preferred worldviews. There is no objective standard for “how continuous is continuous?”
Two more points about continuity. We have emphasized that we can and must engineer continuity rather than take it for granted. Unfortunately, it is too easy to imagine a world in which none of the recent incidents had come to light. We remain dependent on voluntary transparency from frontier AI companies. Embedded evaluation is a great step forward, but it should not be voluntary. We have long been in support of much stronger transparency legislation and reaffirm that view here.
Continuity is important to our worldview because “Long before a system would be granted access to consequential decisions, it would need to demonstrate reliable performance in less critical contexts. Any system that interprets commands over-literally or lacks common sense would fail these earlier tests.”
We’ve now had significant examples of systems that fail these prerequisites. This is the crux. How will AI developers — and their customers, and policy makers, and society at large — react to the recent loss-of-control incidents? That reaction will determine whether or not the second part of the continuity hypothesis (the ability to respond to smaller-scale warnings) continues to hold. We consider it a critical test for the usefulness of the AINT framework for AI safety.
We were too confident in AI companies’ ability to take basic control precautions when running evaluations. We were surprised by the lack of organizational maturity within leading AI companies that led to these incidents. Our expectation was that existing legal liability, imperfect as it is, and the risk of brand damage would be a sufficient antidote to such organizational practices. We were wrong. This reinforces the need for policy interventions to move the needle.
Jaggedness and risk-specific defenses
Broadly speaking, AI as Normal Technology argues for slow timelines. This is primarily because of bottlenecks to diffusion, but the essay also has a tentative section that talks about speed limits to progress in AI methods and advances in capabilities. These limits exist despite the possibility of recursive self-improvement. We take RSI seriously, but we think many of the bottlenecks to superintelligence are external and won’t be overcome by improving computation.
That said, we underestimated the importance of jaggedness. Not only is AI’s capability profile at any given moment highly jagged, so is the rate of improvement in different domains. Combined with the fact that deployment barriers for harmful uses are often lower than for economically productive uses, risks such as in cybersecurity can arise rapidly, leading to periods where the offense-defense balance is upset since defenders might not have time to adapt. Thus, we are no longer confident in our earlier prediction that the offense-defense balance will continue to hold even with advances in AI.
At the same time, jaggedness only strengthens our view that it is more important to mitigate specific risks rather than trying to solve all safety risks through alignment. While risks might arise rapidly, they do so in specific areas, and we should be prepared to rapidly strengthen our defenses in those areas — and ideally do so pre-emptively. For example, there are known interventions that would help mitigate the biosecurity risks from advanced AI models, such as DNA synthesis screening, which we should invest in now.
Is AI safety on track?
Because many people are only familiar with the title of the AI as Normal Technology thesis and not its contents, we are often mistaken as downplaying AI risks, though we have repeatedly clarified that that is not our position. Still, it is important for us to be explicit about how much urgency there is.
Because the question is a bit fuzzy, we have said different things at different times. We’ve expressed views along the lines of “There’s work to do, but we are on track” when it comes to AI safety. But in other writing, including in the AI Snake Oil book many years ago, we’ve been clear that we’re bad at reacting to even normal general-purpose technologies and that even before AI, we chronically underinvest in protections against catastrophic risks, such as pandemics, which are arguably amplified by AI.
It is important to reiterate that message. Despite recent increases in investment, we still don’t think there is nearly enough investment in cyber-defense. Biorisk defense investment also remains woefully inadequate. Similarly, there hasn’t been much progress in the policy interventions we called for in AINT, and reaffirmed in the essay on Common Ground between AI 2027 & AI as Normal Technology.
So while we continue to reject the alarmism, and don’t believe that catastrophic risks are imminent, we do think risks are increasing over time because our investments and policies aren’t keeping pace. And while the specific types of investments and policies we call for overlap only partly with that of the safety community, we agree that we are not currently on track.
Conclusion
Reactions to the recent loss-of-control incidents have split the AI safety and cybersecurity communities. How should we reconcile these starkly different responses to the same incident? One way is to consider the central role of worldviews in shaping peoples’ opinions. As we wrote in the AI as Normal Technology essay:
AI as normal technology is a worldview that stands in contrast to the worldview of AI as impending superintelligence. Worldviews are constituted by their assumptions, vocabulary, interpretations of evidence, epistemic tools, predictions, and (possibly) values. These factors reinforce each other and form a tight bundle within each worldview.
When we identify the role of worldviews, the factors underlying these differences in opinion become clear. The AI safety community saw the incident through the lens of their long-running predictions about misalignment risks coming true. These risks had been dismissed as sci-fi scenarios by many people, and the community felt it was vindicated by these early incidents and used this opportunity to push for action by companies.
On the other hand, the cybersecurity community compared the incident to the scale and scope of cyberattacks that they regularly deal with. It was clear that AI companies had not adopted a security mindset, nor had they implemented known control interventions when conducting these evaluations. In other words, the security community was taken aback when an incident that clearly resulted from negligence and largely did not lead to real-world harm led to so much commotion in the AI community.
We applaud both communities for trying to hold AI companies accountable. But a big risk from these polarized responses is that communities form epistemic bubbles and don’t seriously engage with the other side’s opinions. If the two communities fail to find common ground, they won’t be able to develop technical interventions and adopt practices that would clearly improve our ability to alleviate these risks.9
In this essay, we try to offer that middle ground. We synthesize lessons from both communities and offer a path forward. If we act with the appropriate urgency, we can hold AI companies to a higher standard, reduce risks from loss of control, and even tilt attacker-defender balance in cybersecurity back towards defenders.
Acknowledgments. We are grateful to Joshua Saxe, Steve Newman, Stephan Rabanser, Justin Curl, and Rod Moshtagi for feedback and discussions that informed this essay. Joshua Saxe’s writing on this topic has been particularly influential to our thinking.
Further reading
-
How should AI companies operationalize AI control? Guidelight has proposed AI control standards for frontier AI companies to implement existing/known practices. Had OpenAI adopted these practices, it is extremely unlikely the Hugging Face incident would have occurred.
-
Cohen and others argue that AI companies could face criminal and civil liability under CFAA for evaluations where they disable safeguards and it consequently leads to real-world harm.
-
Researchers and practitioners in the AI safety and cybersecurity communities have written a number of essays about these incidents. Essays from the AI safety community include [1], [2], [3] and the cybersecurity community include [4], [5], [6].
For example, in Zvi Mowshowitz’s discussion of the incident, he writes: “The biggest failure, the one that counts in the end, was that the models were severely misaligned”
As an example, consider that nearly every single top-level comment on the Hacker News discussion about a recent OpenAI incident, where its agents attacked RubyGems, is about how the company was negligent.
This is not to say companies haven’t invested in control. There have been many examples of control efforts across AI companies. But so far, they seem to pale in comparison to the effort being put into alignment.
In fact, as we were working on this essay, Harvey AI, a legal AI company, acquired Guardrails, a company that builds control interventions for AI. Their main focus is improving AI control interventions for legal settings.
In our own work we’re seeing log analysis emerge as a specialized skill with some members of our team excelling in it. Of course, real-time monitoring will require a slightly different and broader skillset compared to retrospective log analysis.
The “auto mode” in coding agents is a reasonably successful instantiation of the natural-language-as-security policy idea. It is striking that despite this, it has attracted very little principled research.
There is an ongoing debate about what improvements to AI liability policy should look like. Some arguments emphasize what the existing tort system can already accomplish. Others advocate strict liability, which would not require victims to prove negligence, or strengthening negligence law and combining it with independent oversight. We don’t intend to settle these disagreements here; our point is simply that clarifying and strengthening liability for AI agents can make investments in control a business priority.
The letter supporting open models by a coalition of American AI companies was published only a week after the Hugging Face hack was disclosed. Whatever one thinks normatively, descriptively it seems clear that no demonstration of cyber-capabilities is so striking that it will get people to shift their views toward non-proliferation of open-weight models — if anything, the opposite.